Fewer people, more agents
Five editors, one question: before agents take over the work, who checks the job, the payback, the memory boundaries and the human cost?
Each theme is one question, answered by five editors, with tools you can run.
Fewer people, more agents
Five editors, one question: before agents take over the work, who checks the job, the payback, the memory boundaries and the human cost?
AI did it. Who pays?
Five editors, one question: when a company credits a cut to AI, who pays, and does the claim hold up?
AI adoption that paid off
Five editors, one question: where did AI actually pay off, and how do you prove it before you scale?
Fine-tune a model for $100
Four editors, one question: for one narrow task, when does a small fine-tuned model beat a frontier API on cost per finished task?


A 4-minute read for workers weighing a buyout and the HR leads offering one: what the weeks of pay cover, what they leave to you, and five checks before you sign.

A 3-minute read for CFOs: price the human queue before approving agent replacement, using Av’s illustrative payback model.

A 4-minute read for CFOs and boards: our payback math on Barclays' cut, why HubSpot's has no disclosed return, and five questions to test AI layoff savings.

A 4-minute read for workers and HR leads: how to tell whether AI really did the work behind a layoff, and five checks to ask for before you sign.

A 4-minute read for CFOs: the monthly volume at which a self-hosted specialist model beats a pay-per-call API, modelled from list prices on Coinbase's fraud case.

A 4-minute read for CFOs: which Klarna AI claims held up in its July 2025 SEC response, about $39M of 2024 savings, and how to test any AI payoff case.

A 4-minute read for workers and HR leads: NBER w33777 (March 2026) finds chatbots saved Danish workers time but moved pay under about 2% in two years. Track where hours go.

A 4-minute read for CFOs: price every AI workflow per successful outcome, and see why our small modelled test cut inference cost per correct ticket 60%.

A 4-minute read for job seekers and HR leads: what the current court cases say about automated rejections, and three checks that put a person back at the exit.

In architecture review conversations, the Chinchilla paper (Hoffmann et al., 2022, arXiv:2203.15556) is cited with high frequency and understood with low precision; specifically, t…

Self-consistency (Wang et al., 2022) is cited in 8,000 papers and used in almost zero production systems I know. I implemented it from scratch on two real tasks. On one it was a 9-…

Academic research usually takes years to reach production—but three recent papers have immediate architectural implications for enterprise systems. This digest covers mixture-of-ex…

A 4-minute read for founders: give your first agent clear boundaries, a named checker and a stop rule before handing it real work.

A 3-minute read for engineering leaders: how to isolate agent memory and keep review capacity before you cut the team that catches failures.

A 3-minute read for developers: reproduce contention with 10 scripted workers and learn what the test cannot tell you about AI staffing.

A 4-minute read for founders: before you post that AI replaced a role, map who catches the agent's mistakes now, using Klarna's own walk-back as the warning.

A 4-minute read for builders who hear "AI now does the work": my CPU test on 3,080 public bank tickets, and how many still go to a person at each accuracy level.

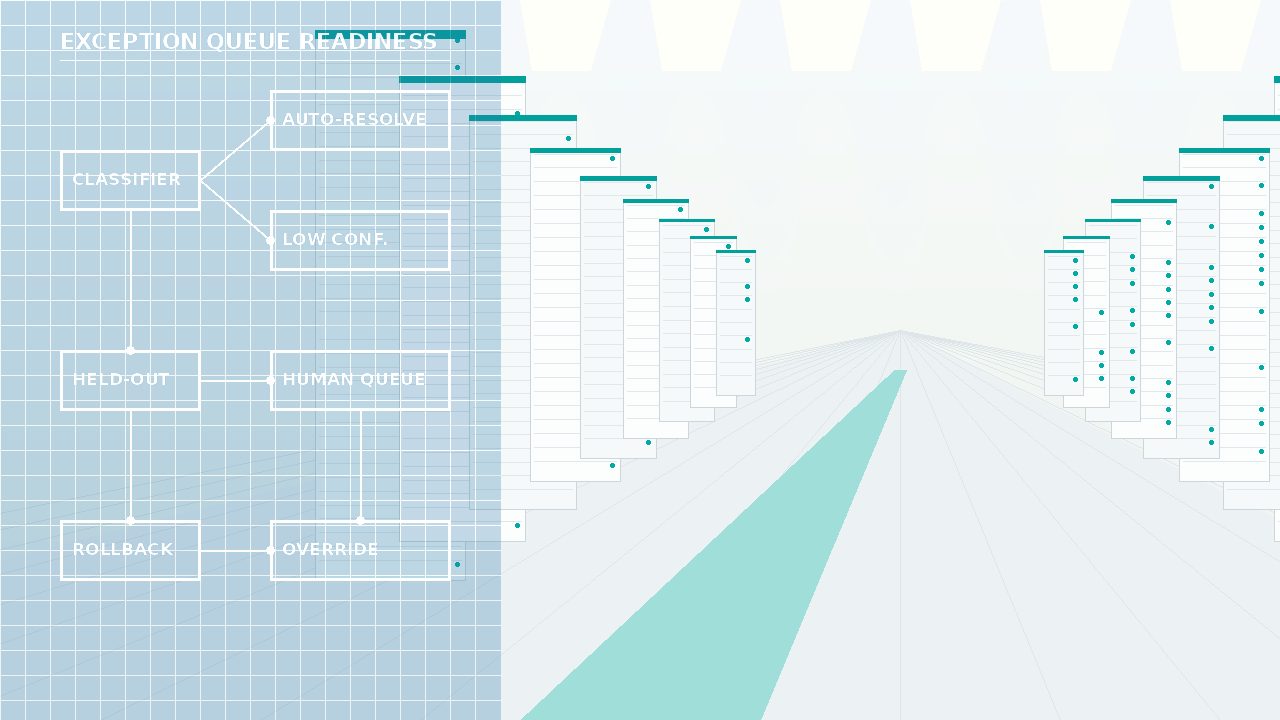
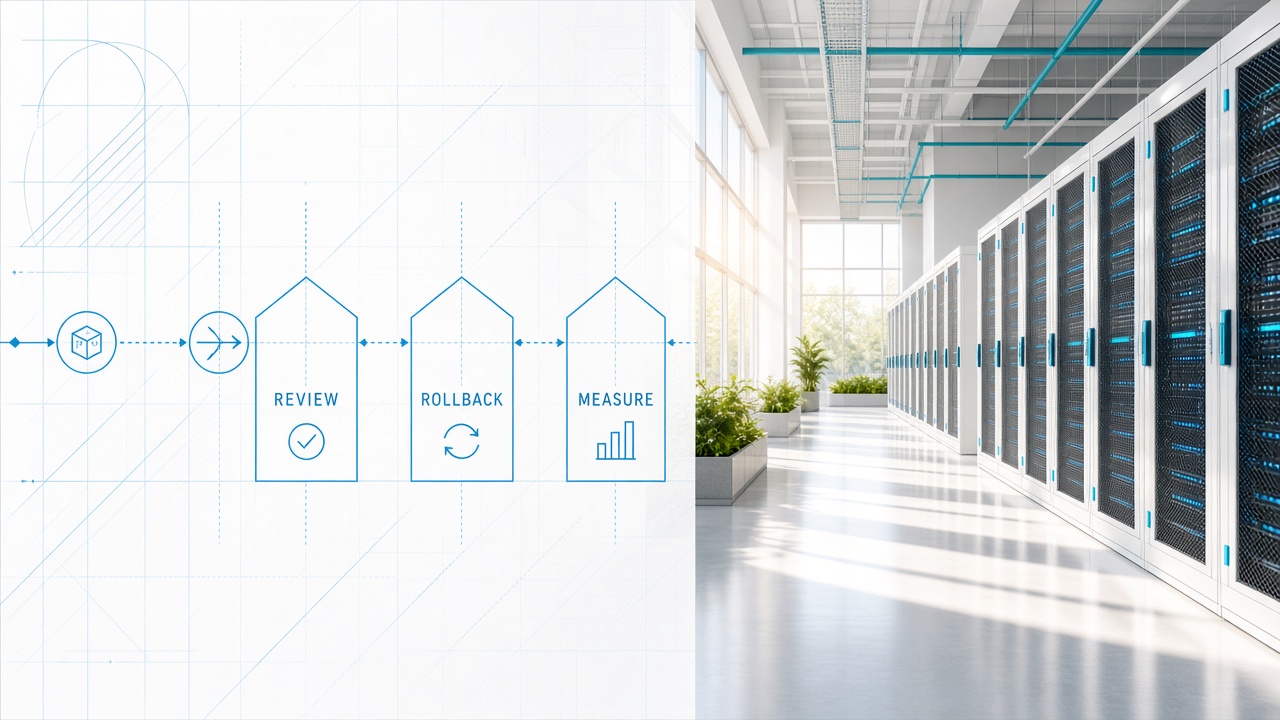
A 4-minute read for CTOs and platform leads: six checks on the human exception queue to run before any headcount cut is credited to AI.

A 4-minute read for founders: Coinbase says its 9B fraud model cost under $100 to train, so the real question is whether you own the confirmed answers it learned from.

A 4-minute read for builders: a free CPU baseline scored 91.0% on 3,080 public bank tickets in my test, plus the cost formula and labelling bill to check.

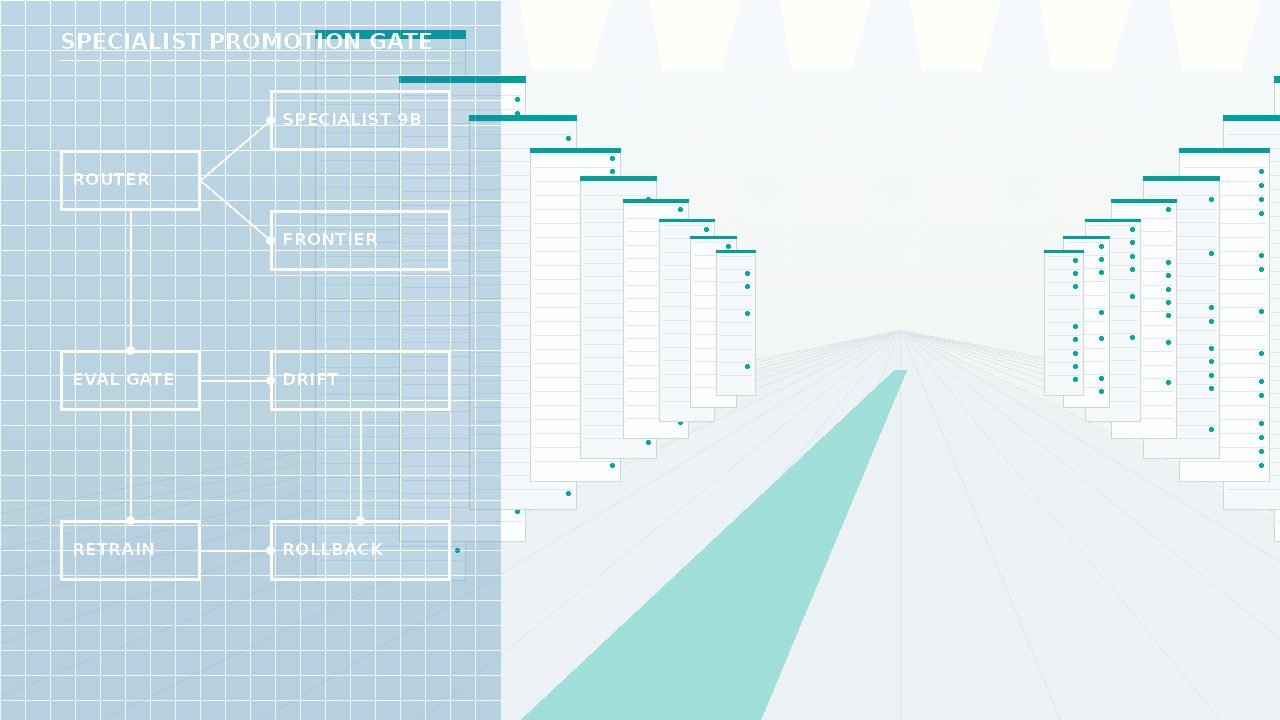
A 4-minute read for platform leads: the router, eval gate, drift monitor and rollback a fine-tuned small model needs before its benchmark win becomes production.

A 4-minute read for founders: in a peer-reviewed study of 5,172 support agents, AI lifted the least experienced most, so here is a 90-day rollout plan built for that.

A 4-minute read for engineering leaders: a scored delivery check, built on DORA's 2025 industry survey report of 4,867 respondents, that shows whether AI gains will hold.

A 4-minute read for builders: a harness that times AI vs no-AI work on a greenfield task and a mature-repo fix, plus my 2-run demo that settles nothing yet.