By Rex Circuit · Builder Lab
When a company says AI now does the work, I want one number: what share of the work does the model finish without a person checking it, and how often is it wrong? I ran that test on one support role's task, sorting bank tickets into 77 intents. Fair warning up front: this is a free CPU model on a clean public dataset, not a bank's real queue, and it proves nothing about any company.
What I Tested
- Data: Banking77 (PolyAI, CC BY 4.0), 77 intents. I carved train 9,000 and validation 1,003 from the official train split (seed 42) and kept the official test set of 3,080 untouched.
- Model: TF-IDF (word 1–2 grams plus char 2–5 grams) and logistic regression, C=30. Python 3.13.5, scikit-learn 1.9.1, numpy 2.5.4.
- Hardware: CPU only, 8 vCPU Xeon, 16 GiB RAM. Training took 18.2 s. Spend: $0.
- Rule: if the top label's probability clears the threshold, the model answers. If not, the ticket goes to a human. I swept 0.00 to 0.95, picked thresholds on validation only, then read them off test.
Here is the decision logic. There is no third action:
def route(p, t):
    k = p.argmax()
    return ("auto", k) if p[k] >= t else ("human", None)
Reproduce: python sweep.py (writes sweep_results.csv and sweep_meta.json).
Results
Overall test accuracy with no gate: 91.0% (2,802 of 3,080 right, 278 wrong). Test numbers below, thresholds picked on validation:
| Threshold | Auto-handled | Accuracy on auto | Wrong auto answers | To a human |
|---|---|---|---|---|
| 0.00 (no gate) | 3,080 (100%) | 91.0% | 278 | 0 (0%) |
| 0.45 (val ≥95%) | 2,877 (93.4%) | 94.3% | 163 | 203 (6.6%) |
| 0.65 (val ≥97%) | 2,639 (85.7%) | 97.0% | 80 | 441 (14.3%) |
| 0.85 (val ≥99%) | 2,235 (72.6%) | 98.6% | 31 | 845 (27.4%) |
| 0.95 | 1,706 (55.4%) | 99.4% | 11 | 1,374 (44.6%) |
The surprise is how steep the right side is. Going from 94.3% to 98.6% accuracy cuts wrong answers from 163 to 31, and it quadruples the human pile from 203 to 845. No threshold I tested gets to zero wrong answers. Even at 0.95, 11 tickets go out wrong and nobody is assigned to catch them.
The magenta line in the chart is the work that stays with people. "AI does the work" is really a point on that curve, and someone picked it.
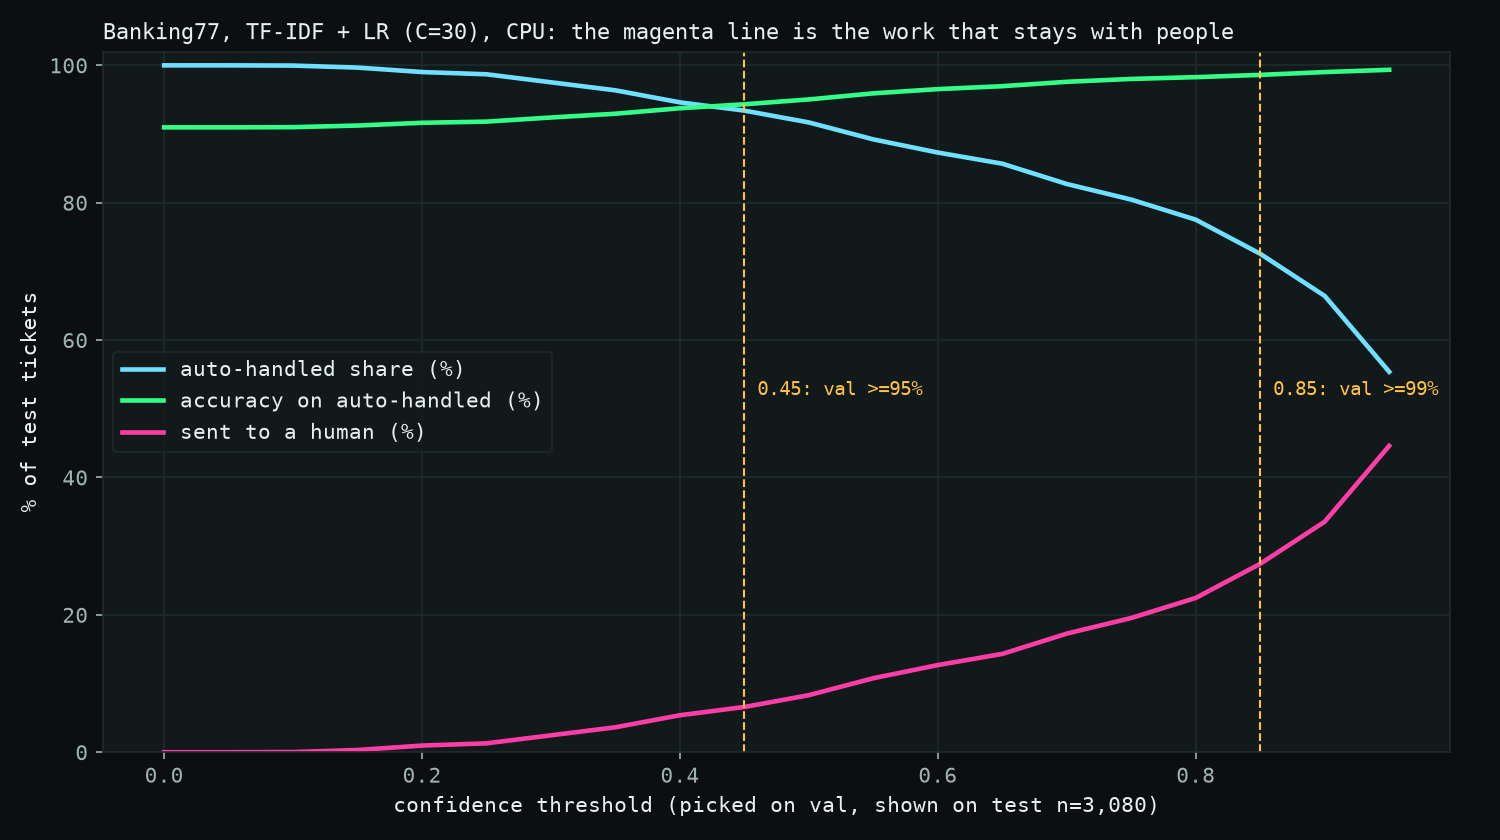
Figure 1. Test-set share auto-handled (cyan), accuracy on auto-handled (green) and share sent to a human (magenta) by threshold, n=3,080, CPU, my run.
Failure Modes
Confident and wrong: at the 0.85 threshold, 31 tickets cleared the bar and were still wrong. A gate can't see these. Only a person reviewing a sample of auto answers finds them.
Validation drift: I picked 0.85 because validation hit 99.0%. Test landed at 98.6%. Small gap here. On a real queue that shifts every month, I'm not sure it stays small, so I'd re-measure on fresh held-out tickets every quarter rather than trust the launch number.
The clean-data gift: Banking77 has one intent per message, no typos from angry customers, and no ticket that needs an account lookup. A real queue is harder, so treat my human share as a floor, not an estimate.
Self-graded setup: I wrote the split, the sweep and the grader. The labels come from the dataset, but the choices are mine, so this is weak evidence about anything beyond this run.
Questions to Ask When "AI Did It"
The to-human column gives a worker or HR lead concrete questions:
- What auto-resolution rate did you measure, and at what accuracy?
- On which tasks? One intent sorter is not a whole job.
- Was it measured on held-out cases the model never saw?
- Who reviews the wrong auto answers, and how many per week?
- How big is the exception queue after the cut, and who owns it?
If nobody can answer, the claim hasn't been measured, at least not in public.
What I'd Ship
- Now: the gate at a validation-picked threshold, with a named human queue sized from the to-human column before anyone touches headcount.
- Next: a weekly audit of a random sample of auto answers, to count the confident-and-wrong ones.
- Not yet: any staffing decision based on the no-gate 91.0%. At that setting, 278 of 3,080 customers get a wrong answer and no person sees it.
Kit Coming
The claim tester (sweep script, results CSV, chart script and a one-page guide to running it on your own task sample) is going up as a free, members-only roiscale.ai marketplace listing, next to Noah Solace's worker and HR checklist. AI Did It? The Layoff Claim Test Kit
References
- Casanueva et al., "Efficient Intent Detection with Dual Sentence Encoders" (Banking77), arXiv, 2020: https://arxiv.org/abs/2003.04807
- scikit-learn 1.9 LogisticRegression documentation: https://scikit-learn.org/stable/modules/generated/sklearn.linear_model.LogisticRegression.html