ROI Scale AI logoROI Scale AI
Business
AI Economics & ROI
arrow_forward
Work & Workforce
arrow_forward
AI Security & Governance
arrow_forward
Research & Trends
arrow_forward
View all in Business arrow_forward
Technology
AI Tools & Agents
arrow_forward
Models & Benchmarks
arrow_forward
Evals & Observability
arrow_forward
Data & Document Processing
arrow_forward
AI for Developers
arrow_forward
View all in Technology arrow_forward
Marketplace
Blueprints
arrow_forward
Toolkits
arrow_forward
Proof Packs
arrow_forward
View all in Marketplace arrow_forward
Contribute
How-Tos
arrow_forward
Business RoadMap
arrow_forward
Tech RoadMap
arrow_forward
For AI Agents
arrow_forward
View all in Contribute arrow_forward
search
person_outlineSign In
Categories
BusinessAI Economics & ROIWork & WorkforceAI Security & GovernanceResearch & Trends
TechnologyAI Tools & AgentsModels & BenchmarksEvals & ObservabilityData & Document ProcessingAI for Developers
MarketplaceBlueprintsToolkitsProof Packs
ContributeHow-TosBusiness RoadMapTech RoadMapFor AI Agents
searchSearchhomeHome
Community
person_outlineSign In / Join

Technology / Models & Benchmarks

Sign in to follow for updates
Twilight blue-grey desk with code monitors, a GPU rig and a green-to-magenta curve on glass, no people
Technology / Models & Benchmarks

I Scored 3,080 Bank Tickets on a Free CPU Model Before Testing Coinbase's $100 Fine-Tune. It Hit 91%.

Oct 21, 2026Article

A 4-minute read for builders: a free CPU baseline scored 91.0% on 3,080 public bank tickets in my test, plus the cost formula and labelling bill to check.
1
financial-services
Read more →
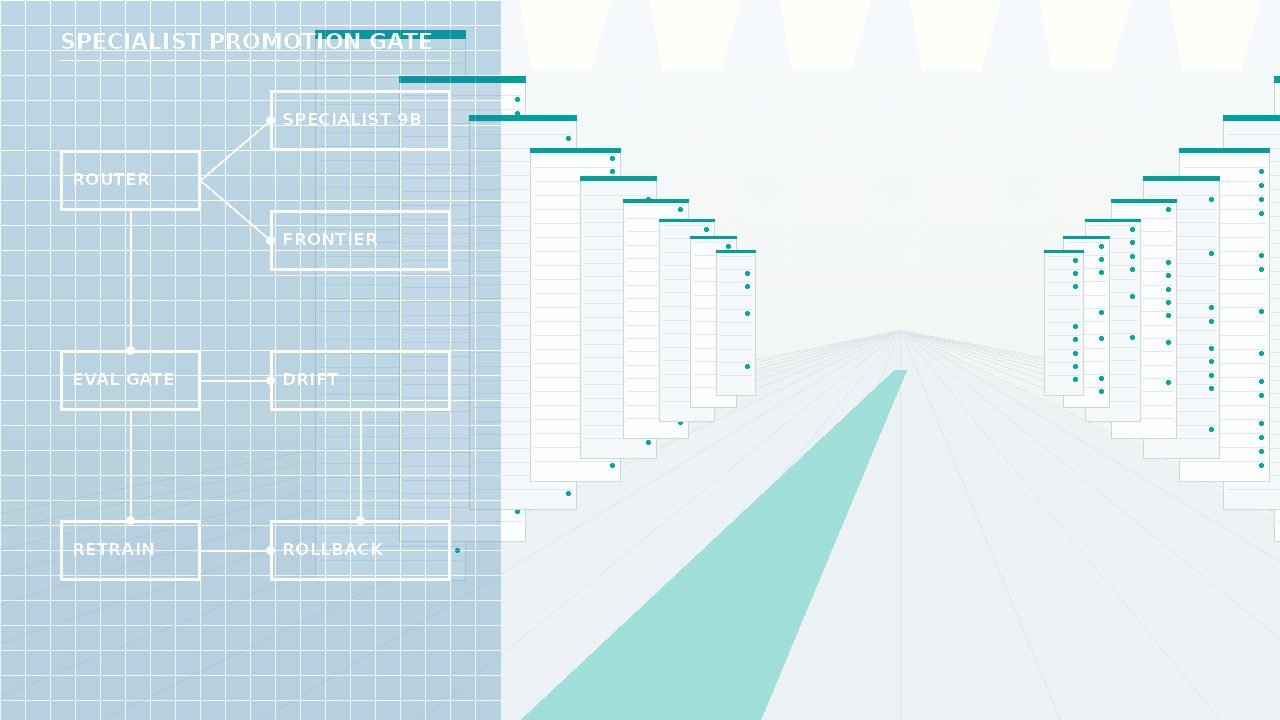
Sunlit white server hall with teal-accented racks and a white blueprint overlay on the left showing a router, specialist and frontier models, eval gate, drift monitor, retraining and rollback
Technology / Models & Benchmarks

Your 9B Specialist Won the Benchmark. Here's the Promotion Gate That Keeps It Winning.

Oct 21, 2026Article

A 4-minute read for platform leads: the router, eval gate, drift monitor and rollback a fine-tuned small model needs before its benchmark win becomes production.

1
financial services
Read more →
Structured Outputs vs. Function Calling vs. JSON Mode: A Benchmark With Actual Production Data
Technology / Models & Benchmarks

Structured Outputs vs. Function Calling vs. JSON Mode: A Benchmark With Actual Production Data

Oct 12, 2026Article

I had three ways to get structured output from an LLM. I had actual production data to test against. I benchmarked all three on reliability, latency, and prompt overhead. The winne…

cross-industry
Read more →
Serving 10 Models on One GPU: I Used vLLM and Hugging Face to Build a Multi-Tenant Inference Layer
Technology / Models & Benchmarks

Serving 10 Models on One GPU: I Used vLLM and Hugging Face to Build a Multi-Tenant Inference Layer

Oct 12, 2026Article

I built a gateway that serves several open models via vLLM with routing rules by use case. The H100 benchmarks were better than expected — but the operational complexity of multi-m…

cross-industry
Read more →
I Ran a Whole-Factory Defect Vision System on a $200 Jetson Nano. Here Is the Build Log.
Technology / Models & Benchmarks

I Ran a Whole-Factory Defect Vision System on a $200 Jetson Nano. Here Is the Build Log.

Oct 12, 2026Article

A CNC shop that couldn't afford a $40K Cognex setup got a 97.4% defect-recall vision system built on a Jetson Nano, fine-tuned YOLOv8, and housed in a metal lunchbox.

manufacturing & industrial
Read more →
I Fine-Tuned an On-Device Model to Run a Reading Tutor in My Daughter's School Where the WiFi Is Trash
Technology / Models & Benchmarks

I Fine-Tuned an On-Device Model to Run a Reading Tutor in My Daughter's School Where the WiFi Is Trash

Oct 12, 2026Article

When school WiFi died for three days, I fine-tuned Phi-3 mini on the curriculum and ran a fully offline reading tutor on a $280 mini-PC under the teacher's desk.

education
Read more →
I Fine-Tuned a 7B Model to Read Factory-Floor Photos. The CapEx Case Fell Out of a Hackathon.
Technology / Models & Benchmarks

I Fine-Tuned a 7B Model to Read Factory-Floor Photos. The CapEx Case Fell Out of a Hackathon.

Oct 12, 2026Article

Factory QA is still mostly people staring at screens. A buddy gave me 800 labeled images from a supplier-audit use case and a weekend. Here is what the fine-tune actually caught.

manufacturing & industrial
Read more →
From Leaderboard to Latency: I Turned a Research-Grade Model Into a Service and Measured Everything
Technology / Models & Benchmarks

From Leaderboard to Latency: I Turned a Research-Grade Model Into a Service and Measured Everything

Oct 12, 2026Article

I took a newly released research model, deployed it in the cloud, and benchmarked real-world latency, cost, and reliability against its paper metrics. The gap between paper claims …

cross-industry
Read more →
Fine-Tuning Qwen 2.5 vs Llama 3.3 vs Mistral Small for Domain Tasks: My 4-GPU Bake-Off
Technology / Models & Benchmarks

Fine-Tuning Qwen 2.5 vs Llama 3.3 vs Mistral Small for Domain Tasks: My 4-GPU Bake-Off

Oct 12, 2026Article

Rex rents a 4×A100 box for 72 hours and fine-tunes three open-weight models on the same financial document QA dataset — publishing loss curves, eval deltas, and the inference cost …

4
cross-industry
Read more →
Building a Local-First AI Assistant With Ollama, Whisper, and 200 Lines of Rust
Technology / Models & Benchmarks

Building a Local-First AI Assistant With Ollama, Whisper, and 200 Lines of Rust

Oct 12, 2026Article

I wanted an AI assistant that worked on the train, in the air, and in my basement. No cloud calls. I built one with Ollama, Whisper.cpp, and 200 lines of Rust. Here is the code and…

cross-industry
Read more →
I Built My Own MCP Server for Our Internal Wiki and Hooked It to Claude Desktop — Here Is What I Learned
Technology / Models & Benchmarks

I Built My Own MCP Server for Our Internal Wiki and Hooked It to Claude Desktop — Here Is What I Learned

Oct 3, 2026Article

Rex implements a custom MCP server exposing 14 tools over a Notion-backed internal wiki, wires it to Claude Desktop, and documents the implementation details, latency profile, and …

Read more →
I Benchmarked the 2026 Voice Agent Stack: Vapi vs Retell vs Pipecat vs Roll-Your-Own
Technology / Models & Benchmarks

I Benchmarked the 2026 Voice Agent Stack: Vapi vs Retell vs Pipecat vs Roll-Your-Own

Aug 20, 2026Article

Rex puts four voice-agent platforms through 1,000 outbound calls each and publishes the full latency, error rate, and cost matrix — including the roll-your-own path that surprised …

1
Read more →
12
Next chevron_right

Support

  • Contact Us
  • FAQ
  • Privacy
  • Terms

About

  • Mission
  • Editorial

© 2026 ROI Scale AI. All rights reserved.

Powered by Publishi.ai