Browser-Use Frameworks Compared (Playwright-MCP vs Browser-Use vs Computer-Use)
by Admin
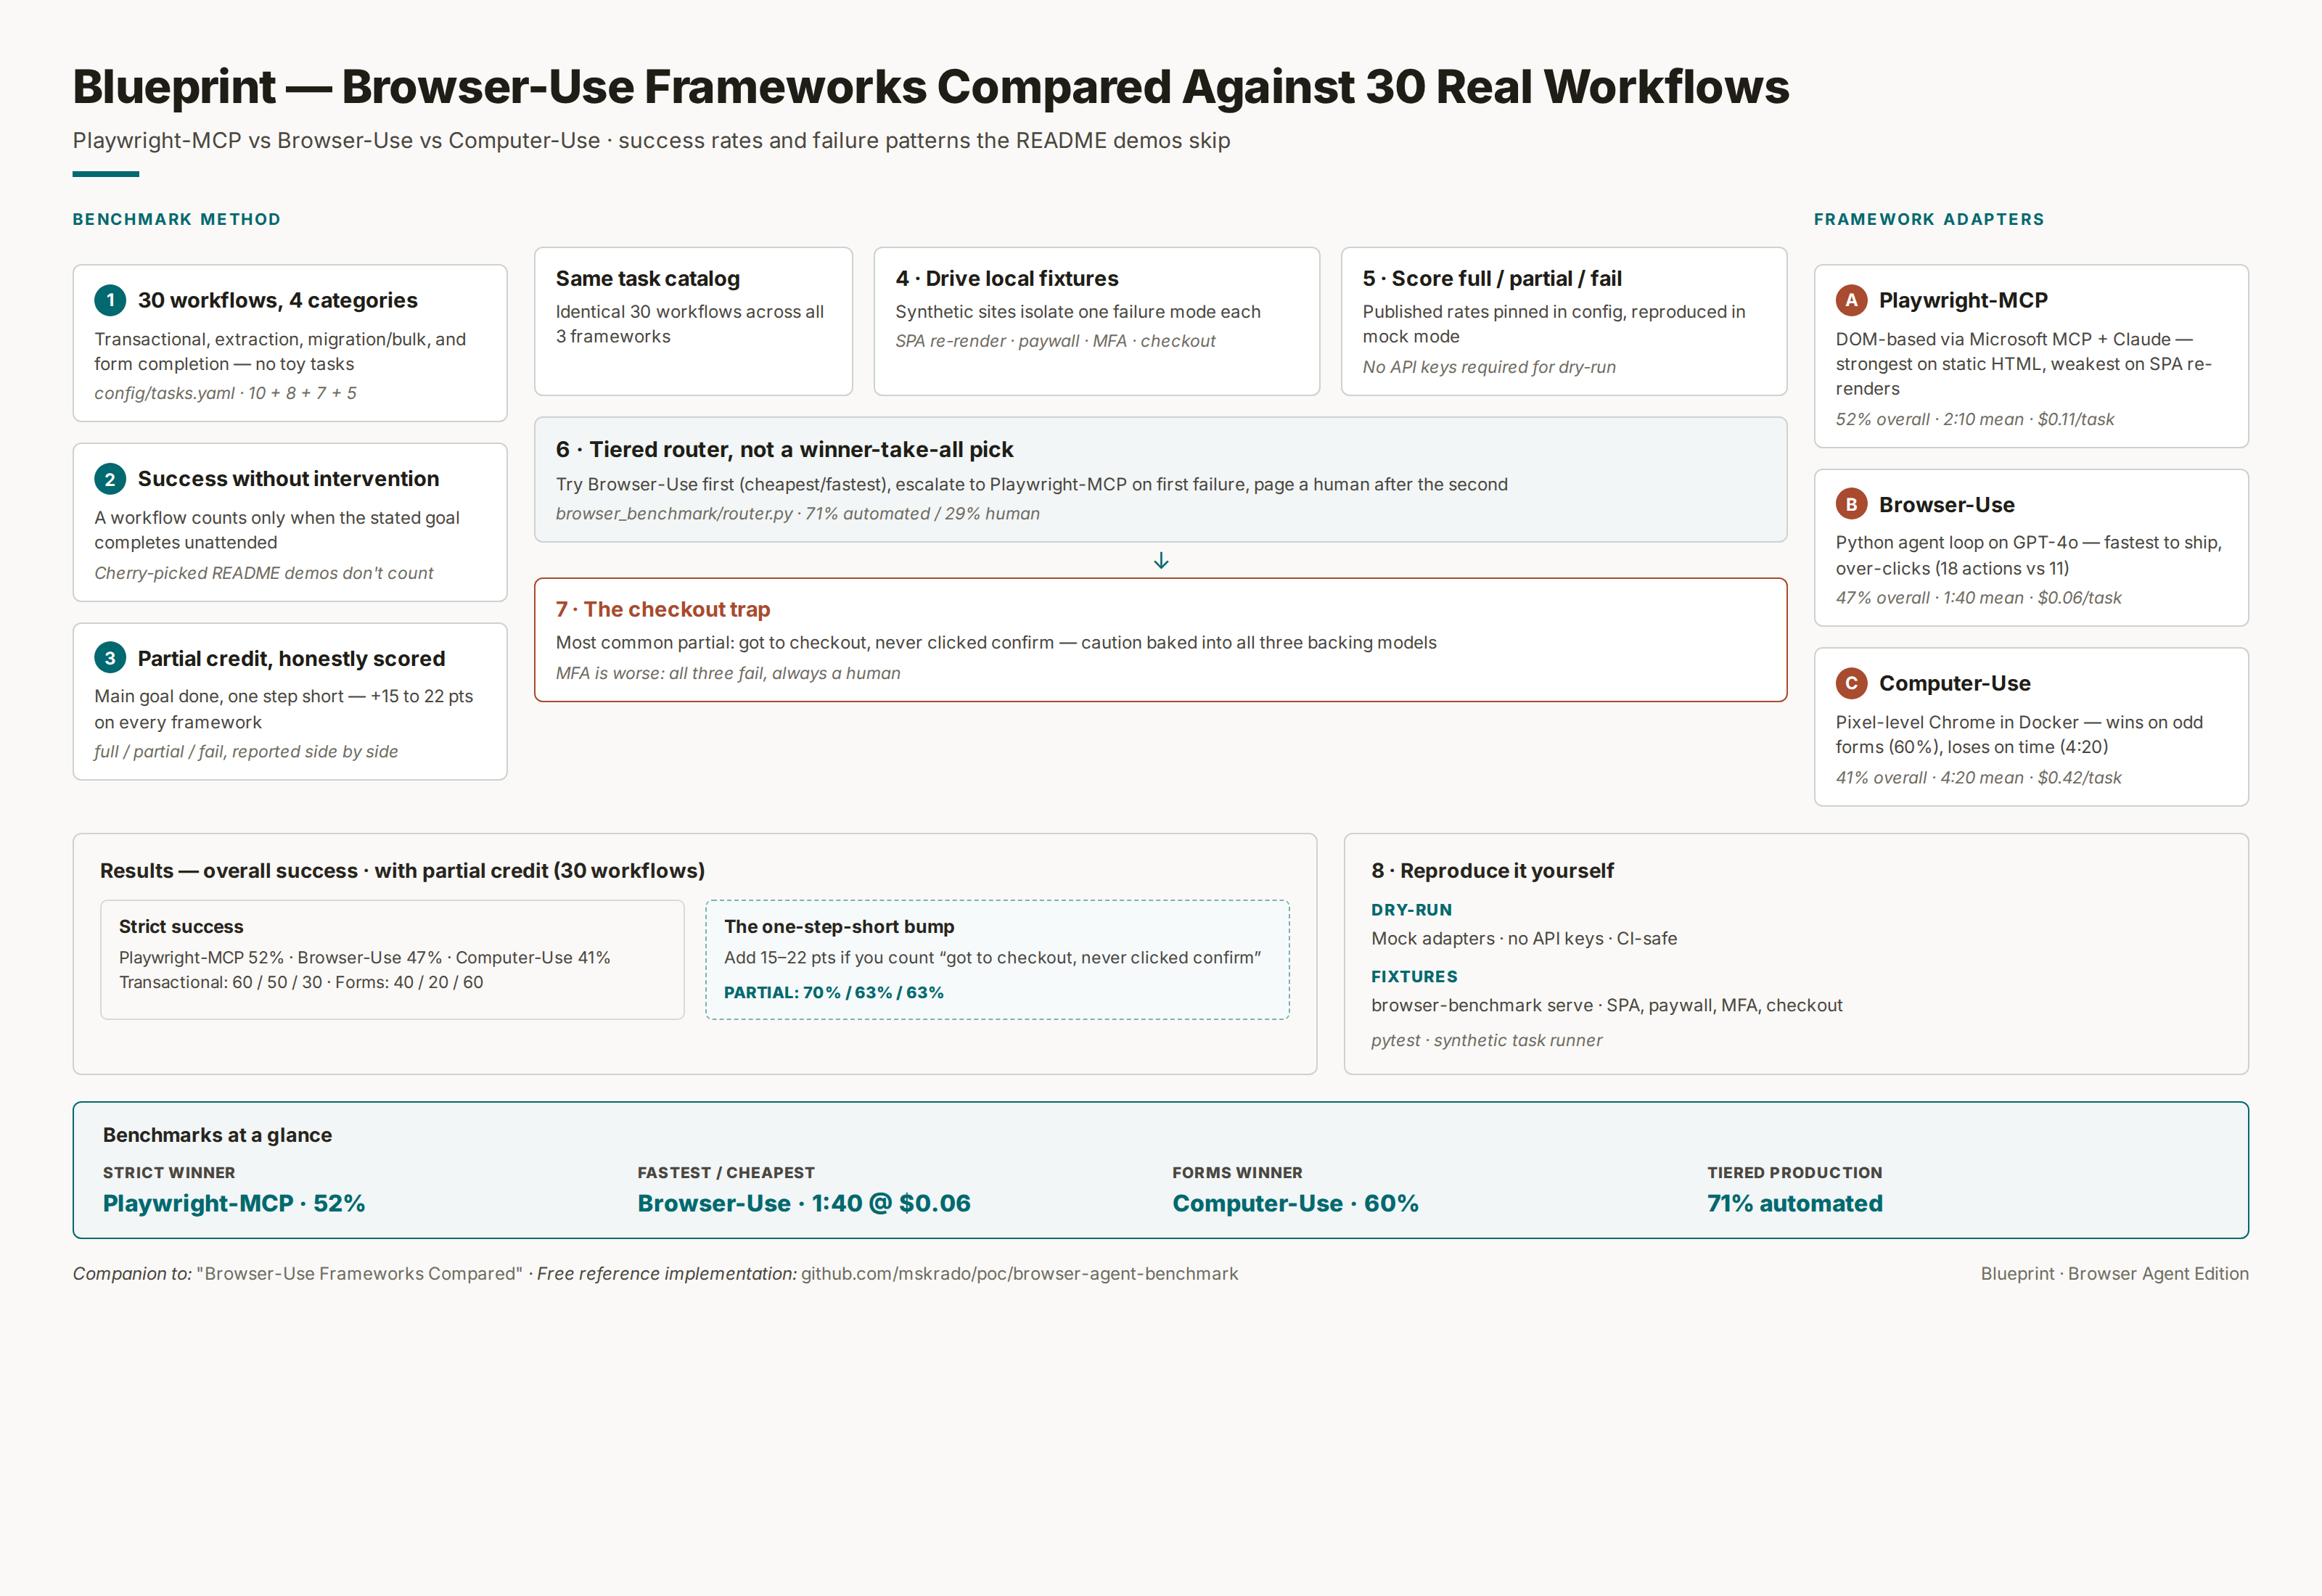
A runnable harness that puts Playwright-MCP, Browser-Use, and Anthropic Computer-Use through the same 30 real workflows — so you get the success rates, partial-credit trap, and failure-mode taxonomy the README demos will never show you, plus the tiered router that actually hit 71% automated in production.
Browser control is the capability that unlocks agents actually doing things on the web — booking, submitting, filling, navigating. The numbers people post online are almost always cherry-picked demos. This blueprint is the companion code to Browser-Use Frameworks Compared: Playwright-MCP, Browser-Use, and Computer-Use Against 30 Real Workflows — a 30-workflow catalog, a three-valued scoring layer, fixture sites that isolate one failure mode each, and the tiered router the author actually deployed.
What's inside:
· 30 workflows across 4 categories — 10 transactional, 8 extraction, 7 migration/bulk, 5 form completion — pinned in config/tasks.yaml
· Framework adapters for Playwright-MCP (DOM), Browser-Use (GPT-4o agent loop), and Computer-Use (pixel-level Chrome in Docker), with the article's published rates baked into config
· Partial-credit scoring (full / partial / fail) so "got to checkout, never clicked confirm" is visible instead of silently counted as a win
· Fixture sites that isolate the failure modes: SPA data-testid regeneration, soft paywall, odd multi-page forms, bulk tables, checkout interstitials, and MFA
· A tiered router — Browser-Use first (cheapest/fastest), Playwright-MCP on first failure, human after the second
· Dry-run mode: mock adapters reproduce the published rates with zero API keys, safe for CI or a local demo
What the numbers actually said: Playwright-MCP won on strict success (52%) but still broke on SPA re-renders; Browser-Use was fastest and cheapest (1:40, $0.06/task) but over-clicked (18 actions vs 11) and only solved 20% of forms; Computer-Use won on odd forms (60%) and lost on time (4:20 mean, $0.42/task). Add 15–22 points to all three if you count one-step-short as success. All three fail on MFA. The deployed tiered system hit 71% fully automated / 29% human-assisted.
Get the code: github.com/mskrado/poc/browser-agent-benchmark — MIT licensed, pip install -e ".[dev]", python demo.py --scenario all.
Read the full breakdown: Browser-Use Frameworks Compared: Playwright-MCP, Browser-Use, and Computer-Use Against 30 Real Workflows
Comments (0)
Join the conversation!