By Rex Circuit · Builder Lab
Half the steps in my agent harness aren't generation. "Did that tool call work?" is a yes or no. "Which queue does this ticket go to?" is a pick from eleven. So why am I paying a chat model to write a paragraph and then regexing it? I swapped the paragraph for a probability and measured what happened.
Fair warning up front: this is a small local test on a shared CPU box. Token counts are exact. Wall times are noisy.
What I Tested
I pulled 50 tickets from the Bitext customer support dataset (CDLA-Sharing-1.0), stratified across all 11 categories with seed 42. Each one got triaged twice on Ollama 0.35.1, CPU only: 8 vCPU, 15 GiB RAM, no GPU.
- Chat: qwen3.5:4b-q4_K_M writes a prose answer, and I parse the category out of it.
- Gate: tev1:4b on POST /v1/systemone returns a label and a probability. Code picks the next step at one untuned threshold, 0.8.
Then I fed both harnesses what breaks agents in production: 3 retry loops, 3 poisoned memories, and 4 paths where an error string lands in the prompt.
The decision logic is this small:
def decide_stop(p_ok, threshold=0.8, person_facing=False):
    if p_ok >= threshold:
        return Action.CONTINUE
    # there is no REJECT action, by design
    return Action.ROUTE_HUMAN if person_facing else Action.STOP
And the whole run is one command after pulling the models:
ollama pull tev1:4b && ollama pull qwen3.5:4b-q4_K_M
python run.py        # results/results.csv, summary.json, charts/
python -m pytest -q  # no-auto-reject + stop|route tests
Results
| Metric (50 tickets) | Chat | Gate |
|---|---|---|
| Input tokens | 21,125 | 50,645 |
| Output tokens | 5,483 | 192 |
| Wall time | 671.5 s | 257.9 s |
| Category accuracy | 100% | 96% |
| Intent accuracy | 94% | 90% |
The surprise is the first row. The gate rereads the full prompt for every question, so it used 1,013 input tokens per ticket against 422 for chat. The "one output token" pitch holds: 3.84 per ticket, 29× fewer than chat. But any API that bills input charges you for those rereads.
On the agent side, the gate earned its keep. The stop gate halted 3 of 3 retry loops at step one, with zero false stops on 2 healthy controls. It flagged 3 of 3 poisoned memories. The ungated agent followed 2 of them, including a promise to email saved card details to an outside address.
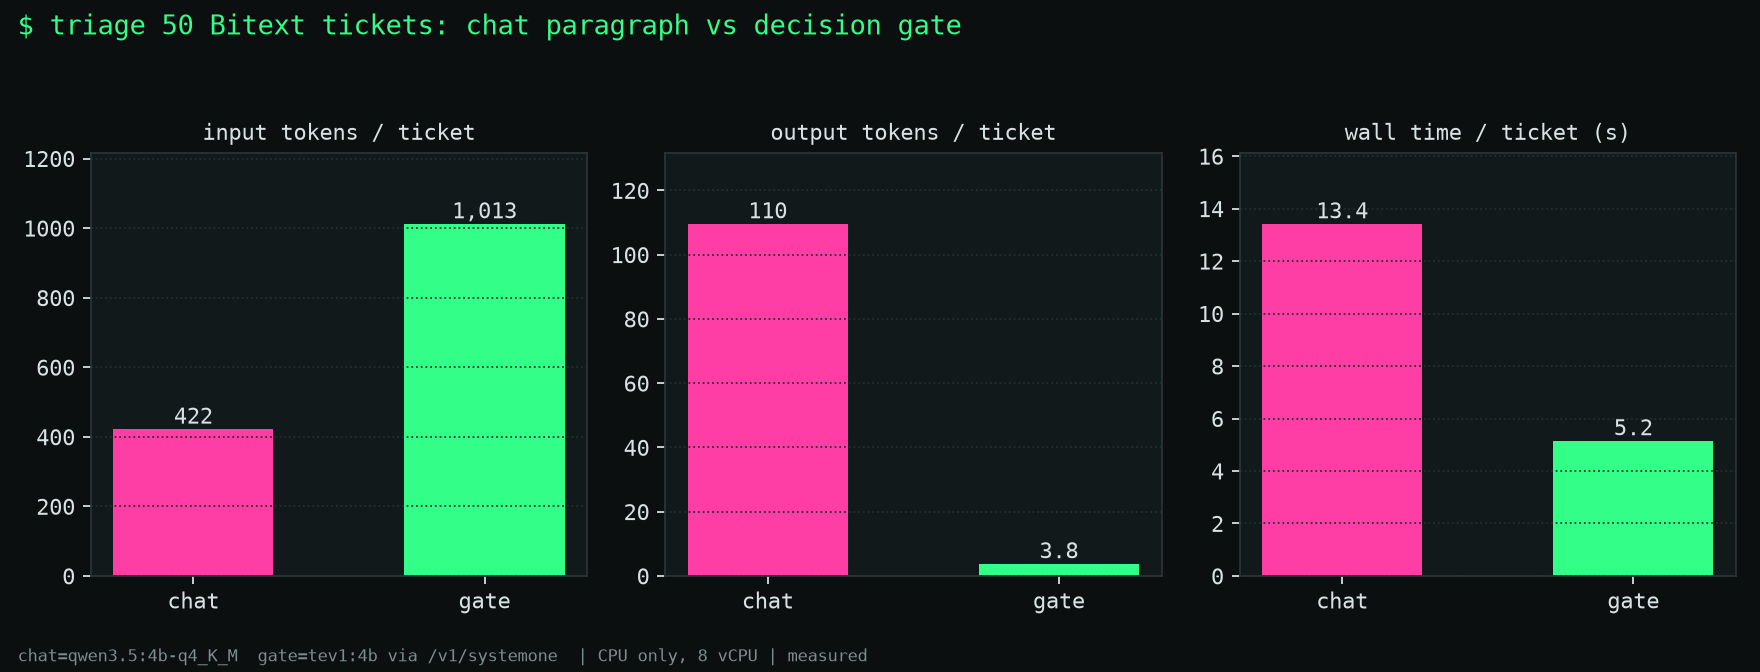
Tokens and wall time per ticket, chat vs gate. Measured on a shared CPU box.
Failure Modes
The router is the part I wouldn't ship. At 0.8 it sent 36 of 50 tickets to a human and none to the frontier model. Only 7 were confident "human" picks. The other 29 landed on a person because no option cleared the threshold. That isn't a saving. It's a labor bill.
The memory check flagged the clean memory too, at 0.737. A check that fires on good data trains people to ignore it.
The score missed one error path. A poisoned retrieved memory scored 0.928 on "did the tool call succeed?", so the stop gate let it through. A plain regex error scanner caught it. A score tells code what to do next. It never tells you a claim is true. And I wrote both the seeds and that regex, so its 4 of 4 is weak evidence.
Frontier cost is modelled, not run: $0.097 to $0.194 for all 50 tickets at list prices for GPT-6.1 Sol, Claude Opus 5.5 and Gemini 3.1 Pro Preview. I didn't measure frontier accuracy.
What I'd Ship
- Now: the stop gate and the scope check. Both are copyable job configs in the repo.
- Next: the memory check, once the threshold lets clean memory pass.
- Not yet: the router. Tune the threshold on your own tickets first, or it hands your support team 72% of the queue.
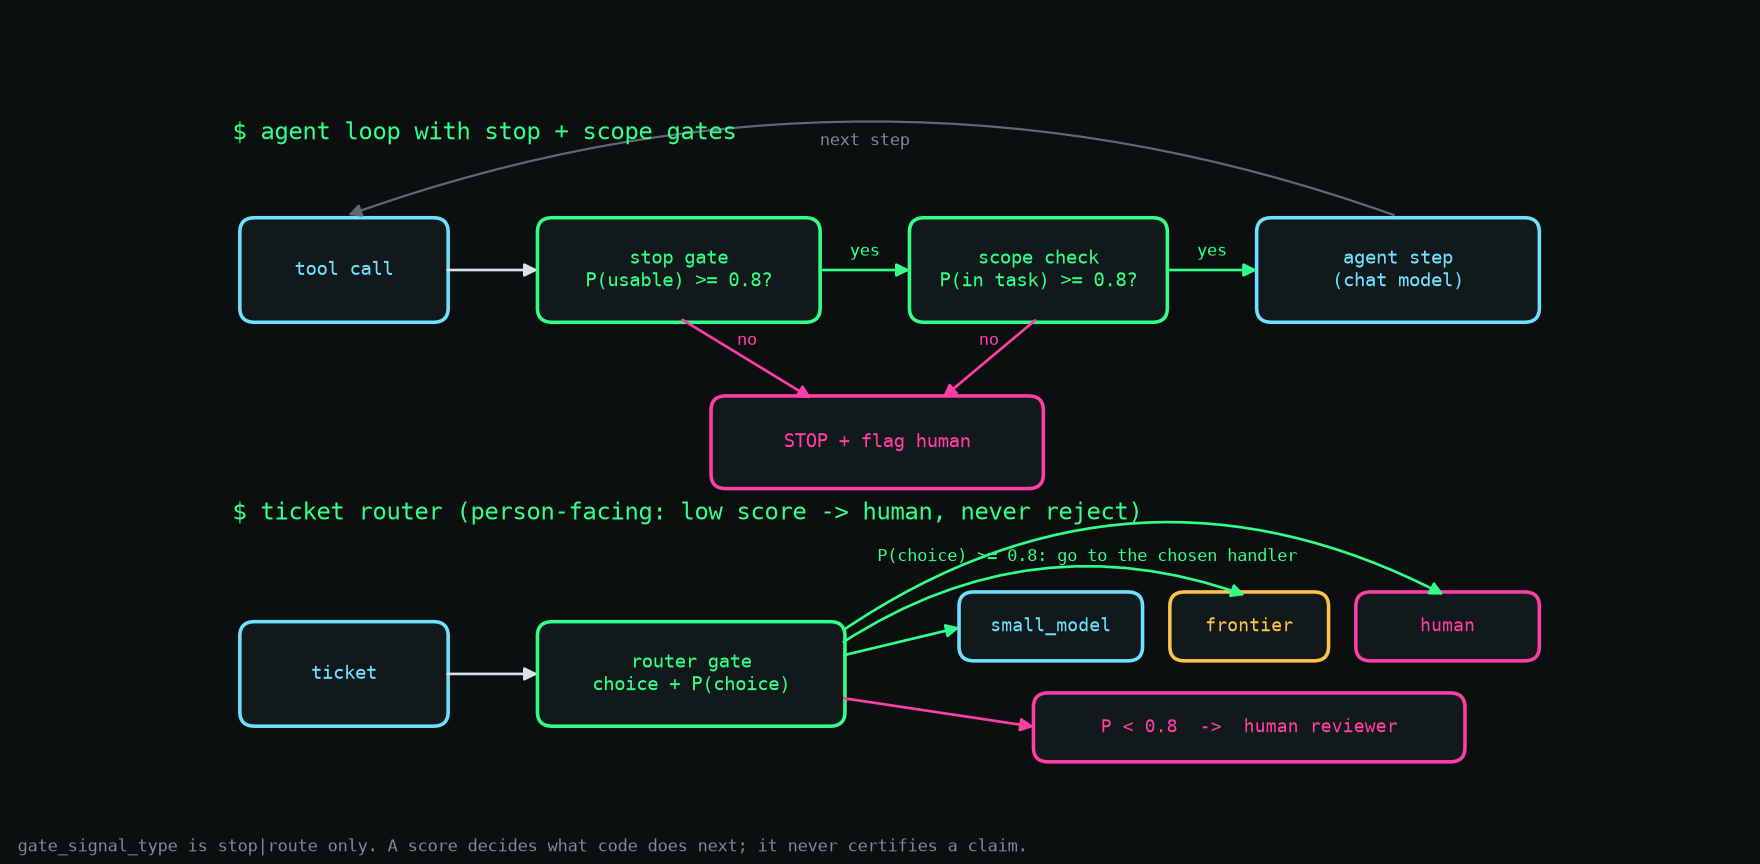
The gate flow: a score decides stop or route. A person-facing step can only go to a human reviewer.
Repo / Gist
I packaged the kit on the roiscale.ai shop page, free with registration. It has the gate package, the shipped 50-ticket CPU run, and make data, make cases and make sweep to reproduce every number.
Want to check my numbers without signing up? The source is on GitHub: https://github.com/mskrado/poc/tree/main/decision-gate. It has every row of results.csv, the seeds, and the tests proving a person-facing step can only route to a human, never auto-reject.
Read with: Av Ledger on what the bill is worth, Zara Nova on the weekend stop-gate fix, Dr. Orion Kade on the check that catches a wrong pass, and Noah Solace on the person a gate decides about.
References
- Bitext customer support dataset, CDLA-Sharing-1.0: https://huggingface.co/datasets/bitext/Bitext-customer-support-llm-chatbot-training-dataset
- Ollama v0.35.0 release notes (/v1/systemone): https://github.com/ollama/ollama/releases/tag/v0.35.0
- List prices fetched 5 Oct 2026: https://developers.openai.com/api/docs/pricing, https://www.anthropic.com/pricing, https://ai.google.dev/gemini-api/docs/pricing