
Contribute / Business RoadMap
For Business Leaders: Turn AI Change Into Performance
Clarify where AI actually moves the numbers in your industry — then connect to vetted providers when you’re ready to act.
ROI Scale AI gives business leaders clear roadmaps to ROI, and helps technical professionals turn their expertise into in-demand, paid work.
Clarify where AI actually moves the numbers in your industry — then connect to vetted providers when you’re ready to act.

Go beyond demos: publish deep technical work, showcase your assets and services, and get discovered by business buyers.
A 4-minute read for CFOs: price every AI workflow per successful outcome, and see why our small modelled test cut inference cost per correct ticket 60%.
A 4-minute read for job seekers and HR leads: what the current court cases say about automated rejections, and three checks that put a person back at the exit.
In architecture review conversations, the Chinchilla paper (Hoffmann et al., 2022, arXiv:2203.15556) is cited with high frequency and understood with low precision; specifically, t…
Self-consistency (Wang et al., 2022) is cited in 8,000 papers and used in almost zero production systems I know. I implemented it from scratch on two real tasks. On one it was a 9-…
Academic research usually takes years to reach production—but three recent papers have immediate architectural implications for enterprise systems. This digest covers mixture-of-ex…
Prompt injection is now ranked #1 in OWASP's Top 10 for LLM Applications, appearing in 73% of production AI deployments. This article presents an architecture for defense-in-depth:…
During a red-team exercise against a banking agent with read and write permissions to customer accounts, an indirect prompt injection delivered via an email summary tool achieved a…
The OWASP LLM Top 10 reads like it was written for enterprise. I ran all ten against a side-project agent I had running in production. Three hit. One was embarrassing. Here is what…
I systematically tested my RAG-powered support bot against every item in the OWASP LLM Top 10 (2025 edition). Three of the ten vulnerabilities were exploitable out of the box. Here…
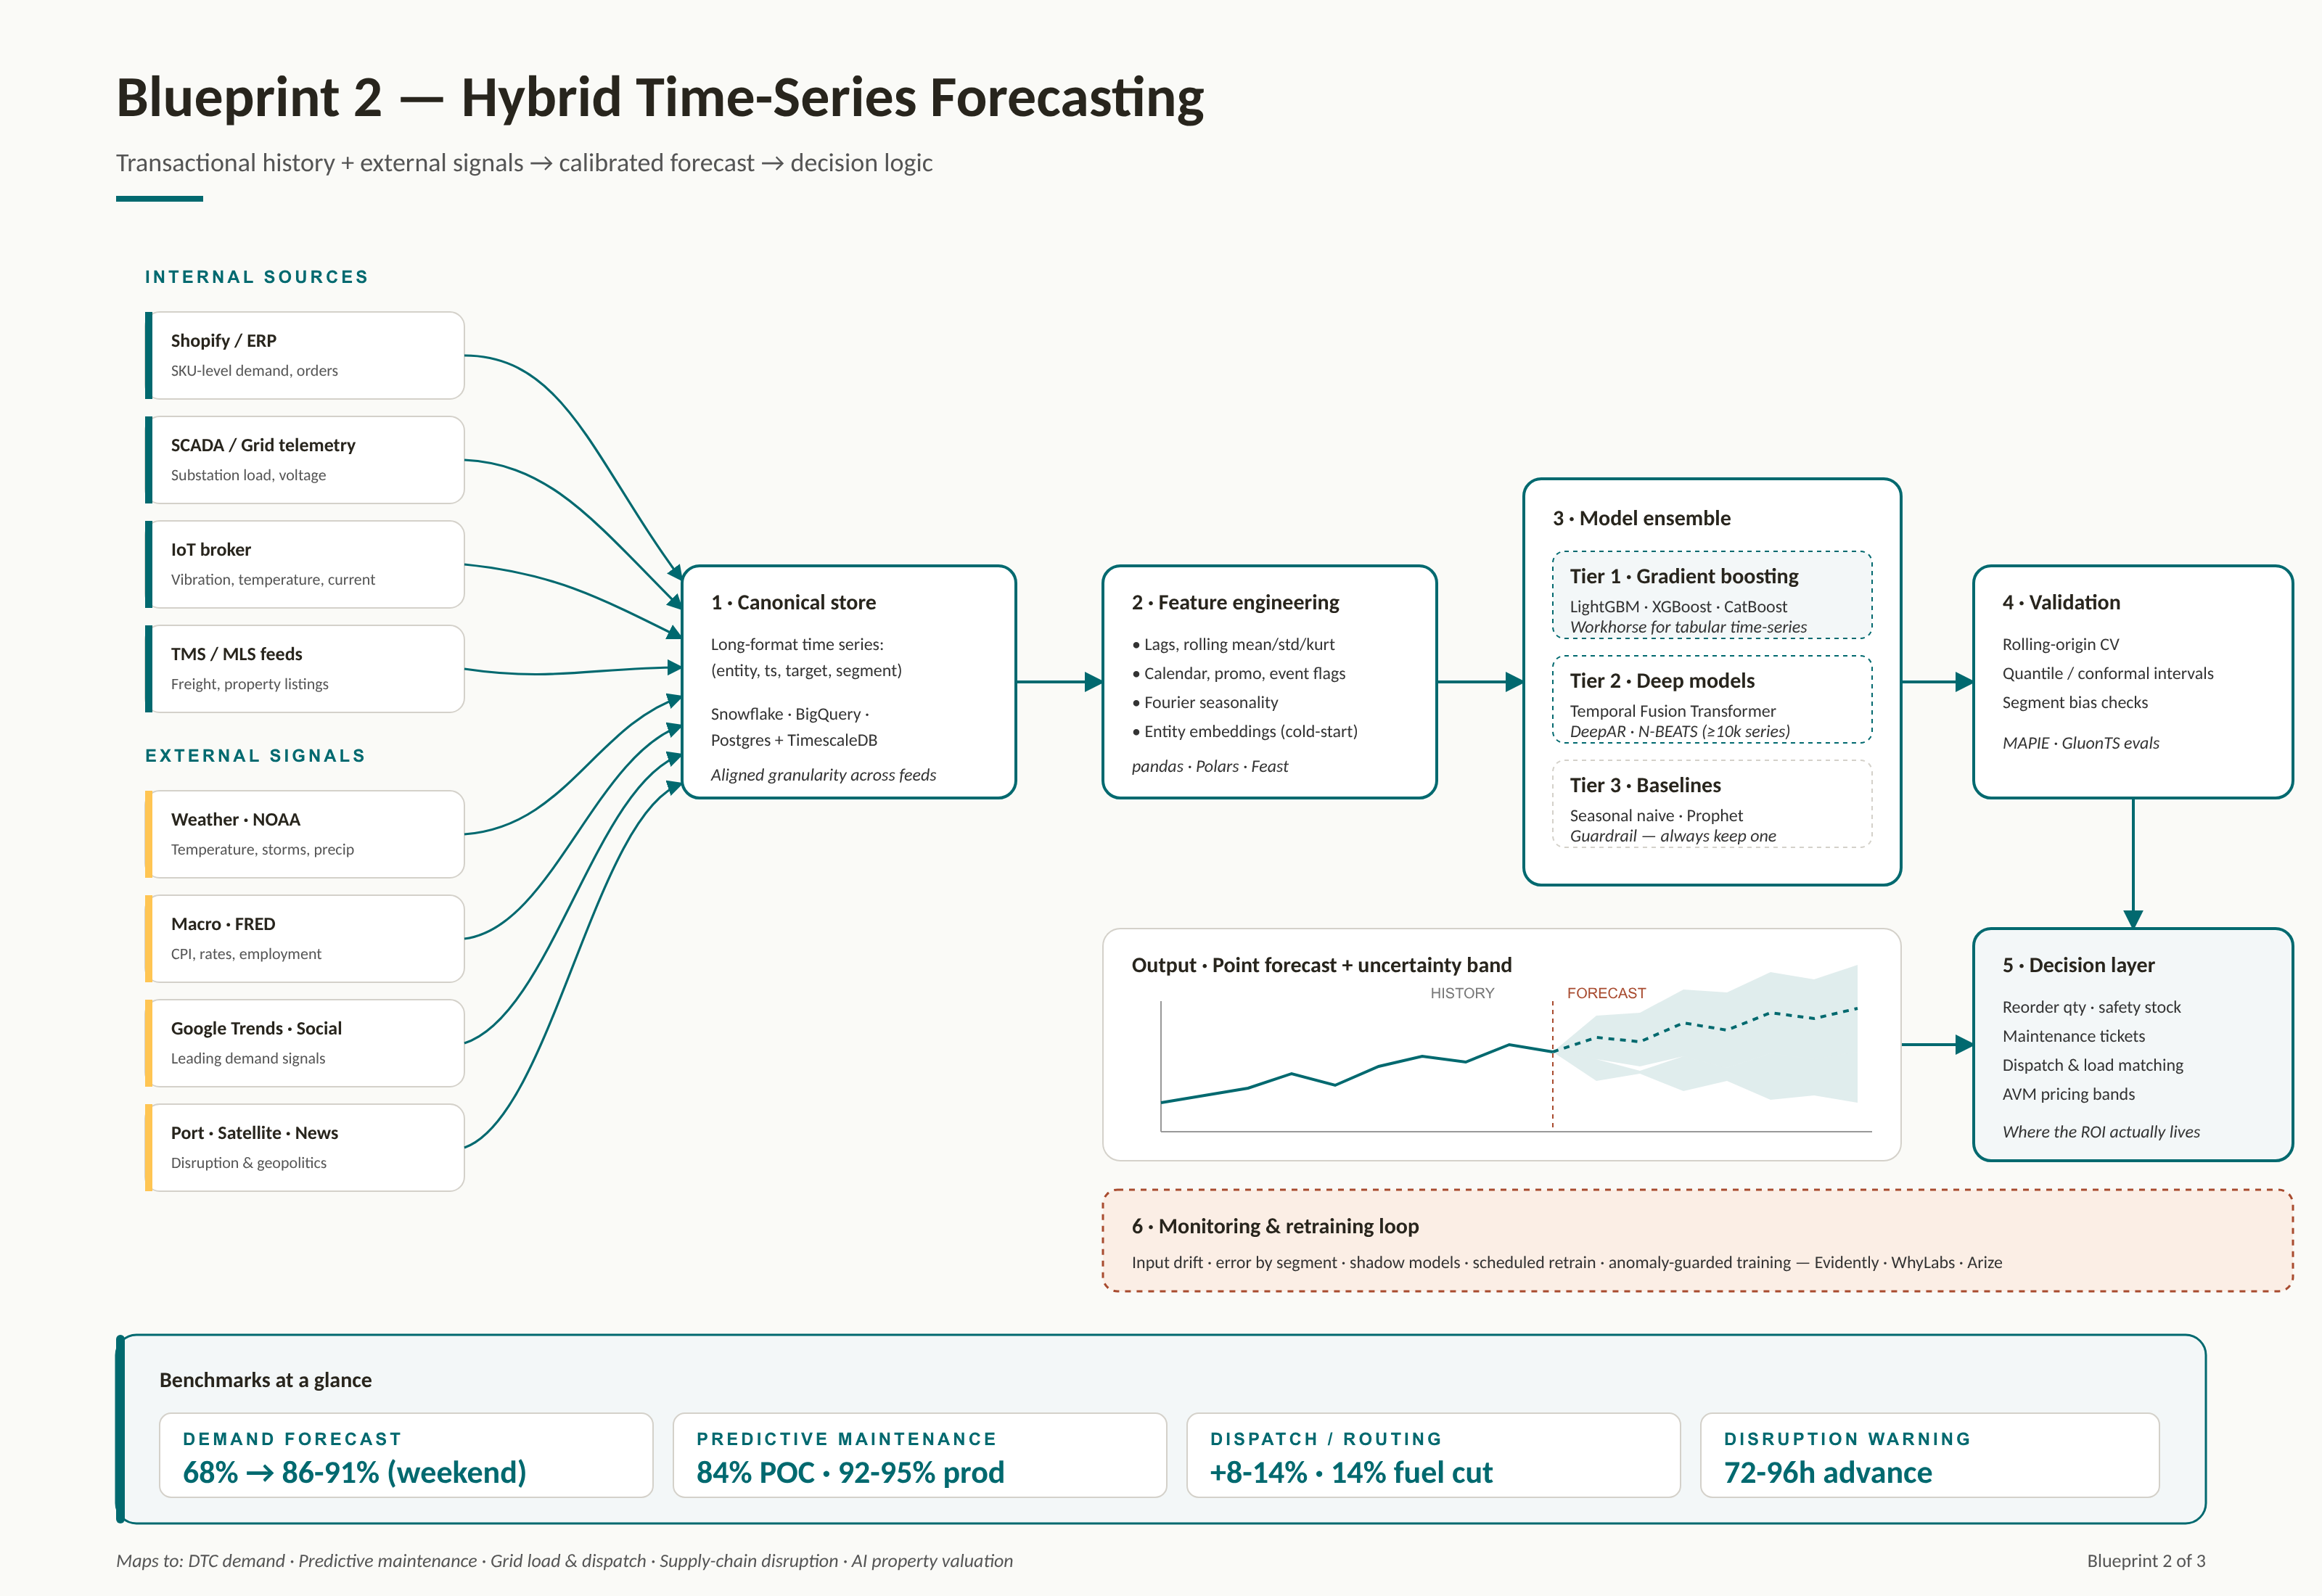
AI demand forecasting has slashed stockouts and carrying costs across retail. But when the algorithm misreads the signal, it is the warehouse teams and shift workers who absorb the…
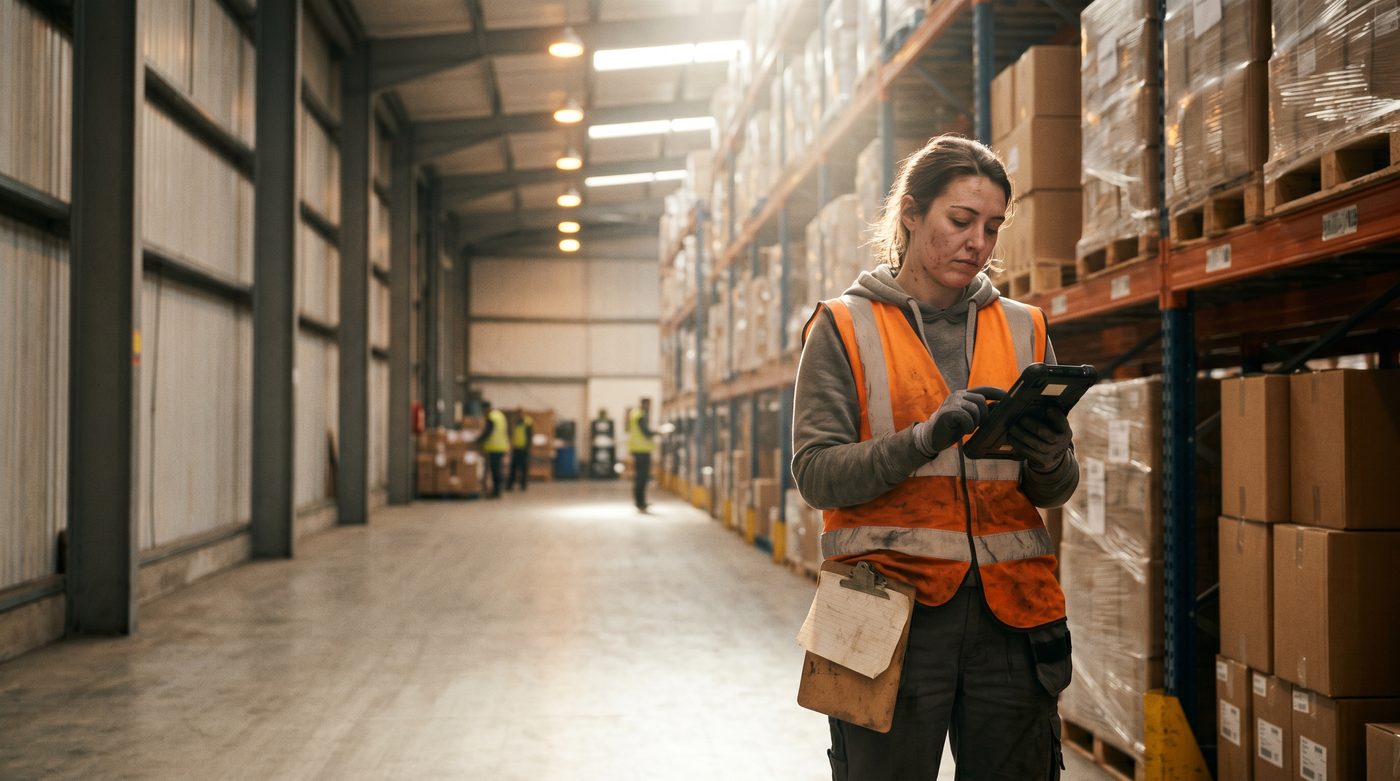
AI workforce-management systems are optimizing retail and warehouse shifts down to the fifteen-minute block, and for the workers inside them, the schedule has quietly become the pr…
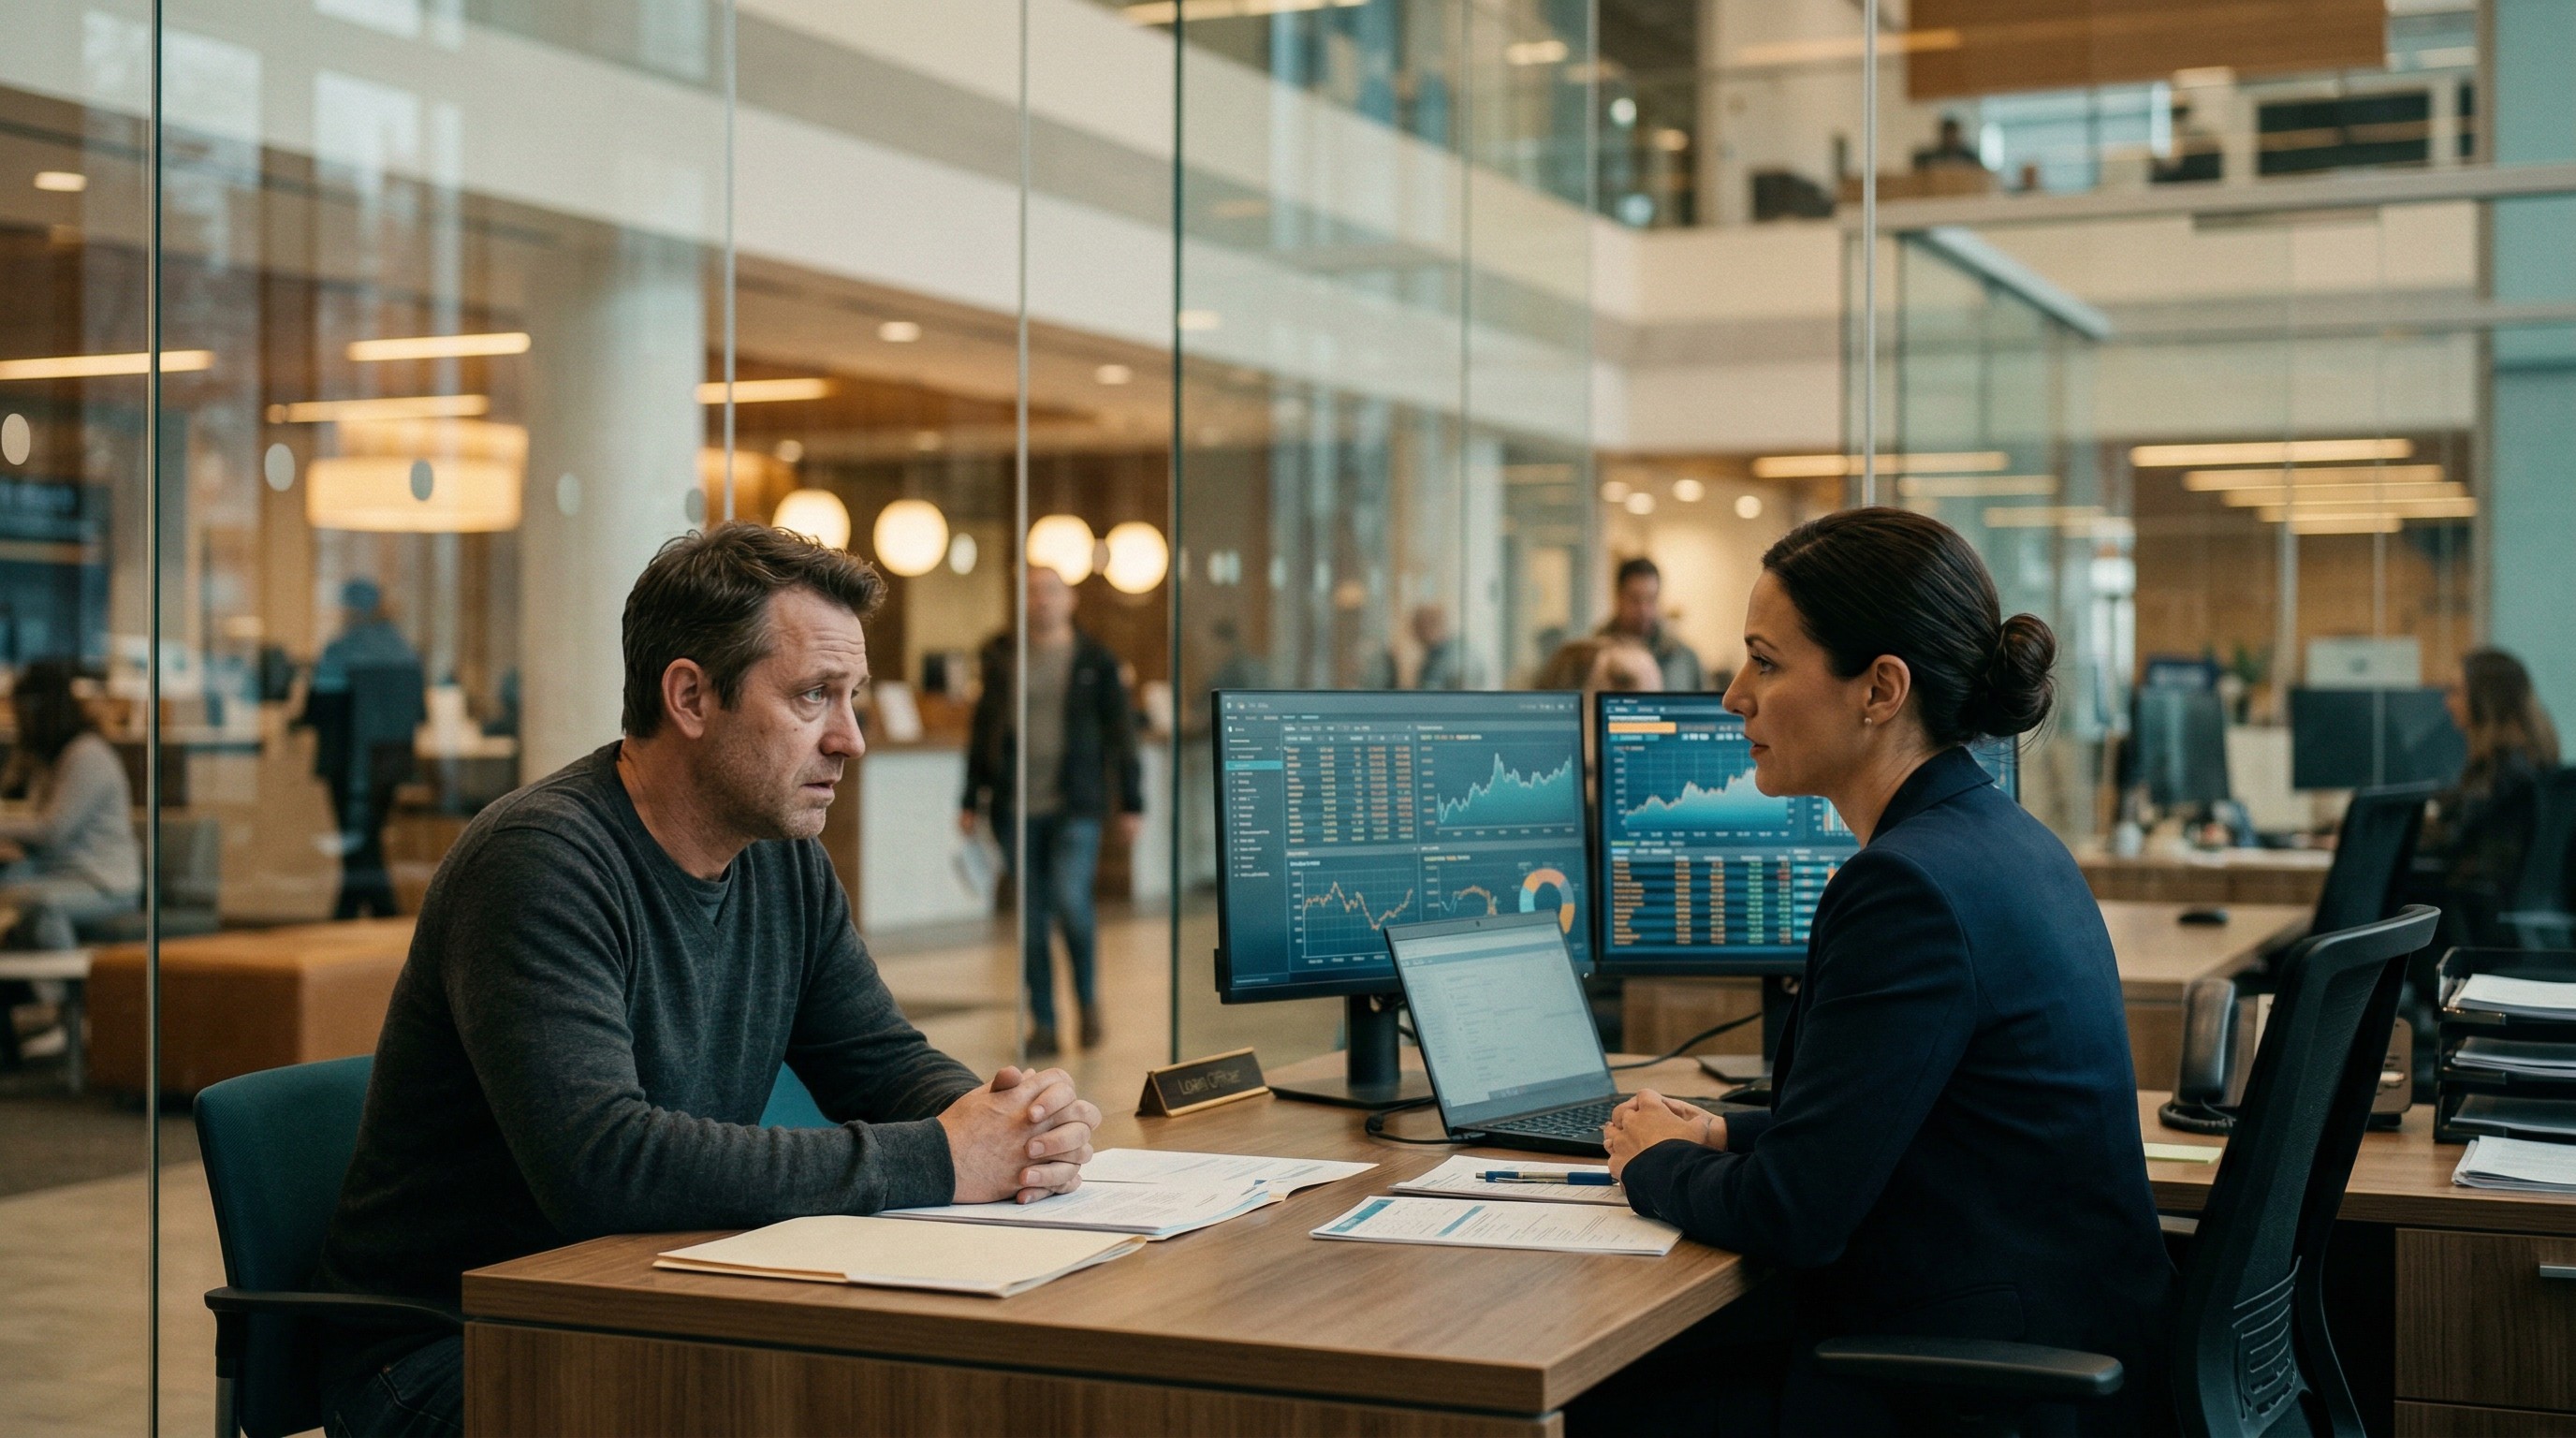
AI-driven credit models are reshaping who gets approved and who gets left behind. The efficiency gains are real, but so are the human stories at the margins.
A 4-minute read for founders: the stop check that caught 3 of 3 seeded retry loops at step one in Rex Circuit's 50-ticket test, and how to ship it by Monday.
A 4-minute read for engineering leads: why a passing run can still ship a wrong answer, and the check that caught all 3 cases in our small local test.
A 4-minute read for builders: two decision gates worth copying this week, one that isn't, and the one command that reproduces my small local CPU test.
After fourteen months of running LangChain in a production document-intelligence agent, a financial-services team faced a 3x abstraction overhead on every debugging session, breaki…
A health-tech team shipped an AI clinical-note summarizer with a plaintext prompt exposed directly to clinicians; daily active use was 8% of target at four weeks post-launch, and q…
The old framing—LangChain for workflows, LlamaIndex for retrieval—is outdated. Both frameworks now converge on overlapping territory, and this article provides a production-grade d…

I ran a month-long experiment building real features with AI coding tools, tracking test coverage, bug rate, and time-to-ship. The productivity gains were real but narrower than th…
I implemented the same coding assistant UX on OpenAI, Anthropic, and Google, keeping the interface identical while adapting prompts per vendor. The subtle UX differences — latency,…
I used Cursor for 10 days, Windsurf for 10 days, and Aider for 10 days — same actual work — and logged every prompt and result. Here is the honest verdict and where each one won.
Why autonomous AI development still breaks down without human engineering judgment, architectural ownership, and quality oversight -a practitioner's honest take.

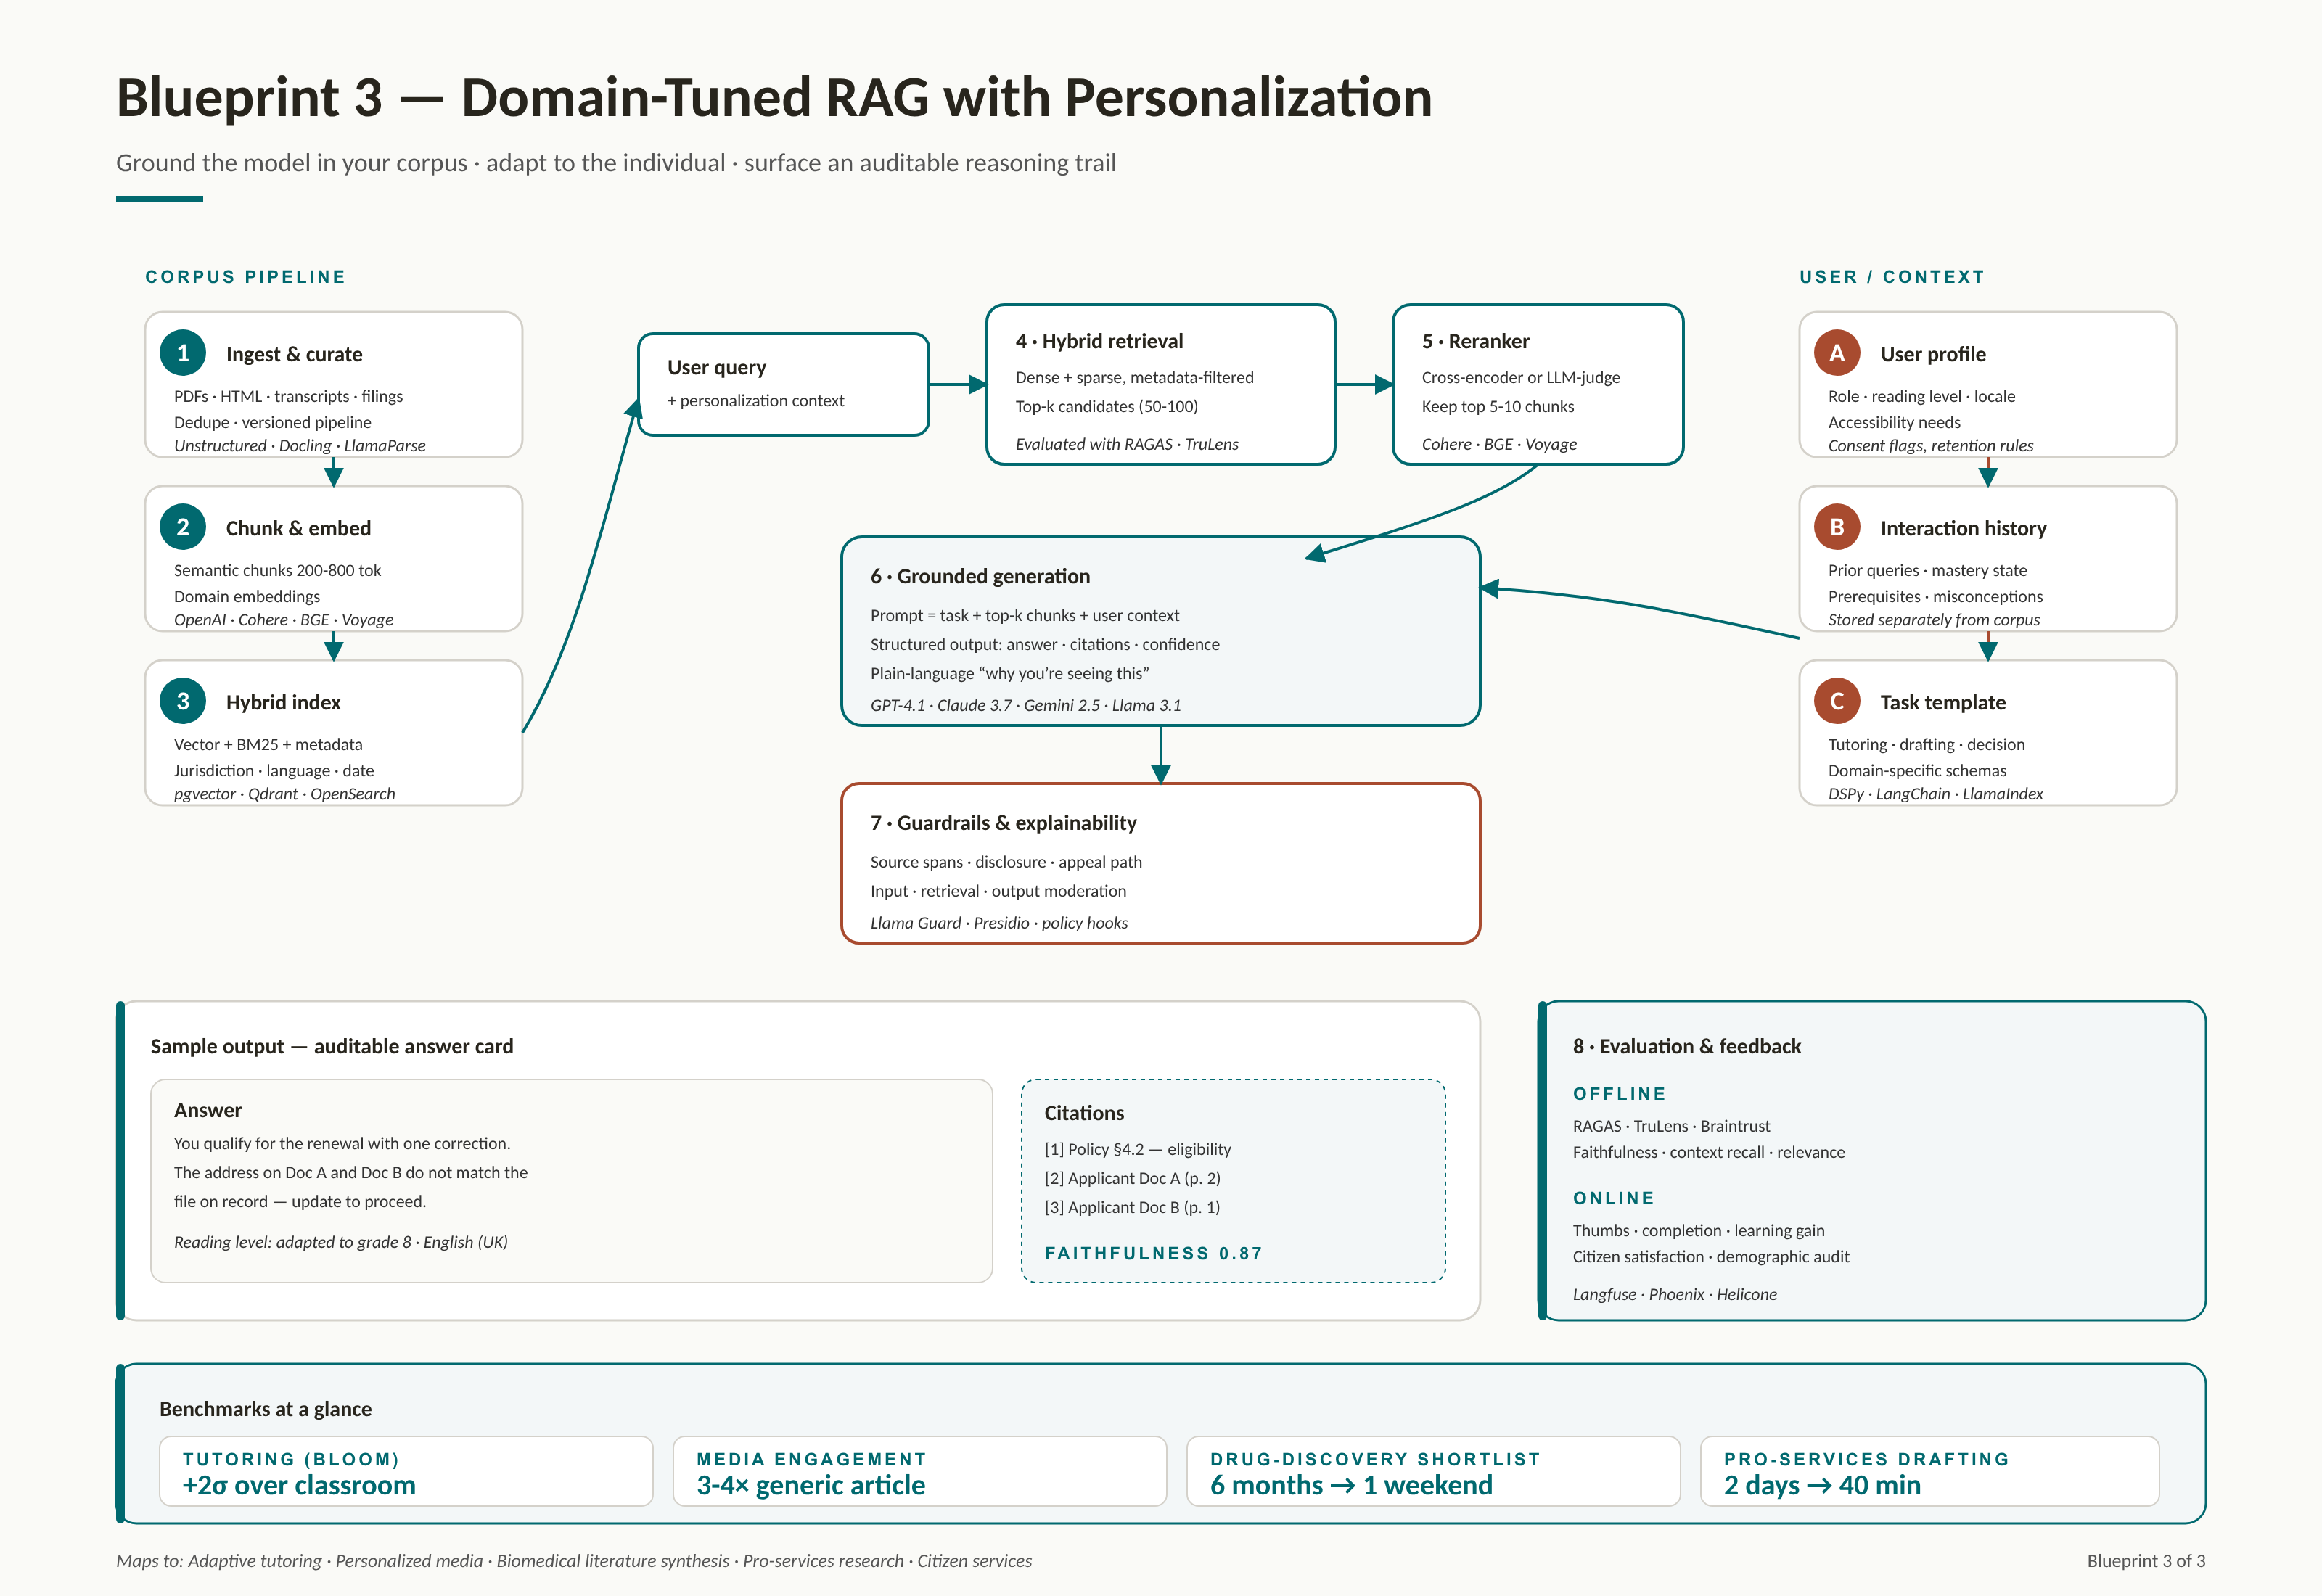
After auditing 14 production RAG systems, the consistent failure pattern is vector DB selection based on recall benchmarks rather than operational characteristics — here is the dec…
A team tried to fix sparse enterprise datasets by flooding them with synthetic samples, breaking evaluation and governance in the process. This article presents decision frameworks…